The idea: retry, but not all at once
Calls over a network fail for short-lived reasons: a restart, a full queue, a dropped packet. Trying again a moment later often works, so almost every client library retries. But a retry is one more request to a server that is already in trouble. If every client retries at the same moments, the retries themselves keep the server down.
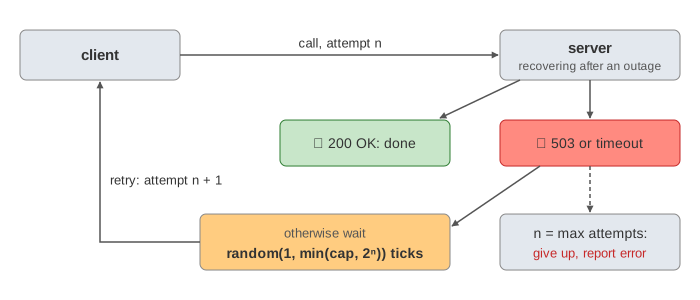
The page runs one scenario. Six clients C1–C6 each call the server at t = 1. The server is down for t = 1–2. From t = 3 it is up but recovering: it serves 2 calls per tick and answers the rest 503; more than 4 calls in one tick overload it and all of them get 503. Each client makes at most 4 attempts. Pick a retry policy and press Next Tick, or run a demo. The timeline marks each attempt ✓ or ✗, and its last row counts the calls the server got in each tick.
Immediate retry: the retry storm
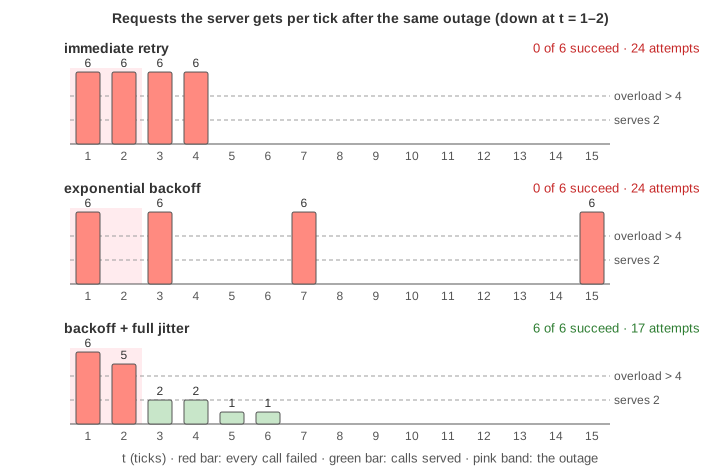
The simplest policy retries at once (here: the next tick). During the outage the server gets all 6 calls every tick. When it comes back at t = 3, it still gets 6 calls at once, more than it can take, so it fails them all again. At t = 4 every client has used its 4 attempts and gives up: 24 calls, none served (Demo 1). In a real system the clients are thousands and each one may retry at several layers, so a short outage turns into a retry storm that keeps the service down long after the original fault is gone.
Exponential backoff
Exponential backoff doubles the wait after each failure: wait = min(cap, base × 2ⁿ) after the n-th failure. Here base is 1 tick and the cap is 8, so the waits are 2, 4, 8. A client that keeps failing calls less and less often, which cuts the load during a long outage. The cap keeps the wait from growing without bound.
But on its own, backoff does not break up the herd. All six clients failed at the same tick, so they compute the same wait and come back at the same tick: t = 3, 7 and 15, six calls each time, and the server is idle in between (Demo 2). Each wave overloads it, and again nobody gets through. Backoff spread the attempts over time but kept them synchronized.
Jitter
Jitter adds randomness to the wait so that clients that failed together retry apart. With full jitter each client waits a random time up to the backoff: wait = random(0, min(cap, base × 2ⁿ)). The page counts in whole ticks with base = 1, so it draws from 1 to min(cap, 2ⁿ). On the page the same six failures now come back as 5, 2, 2, 1 and 1 calls in the following ticks. From t = 3 the server gets at most 2 per tick, serves them all, and every client succeeds by t = 6 with 17 calls in all (Demo 3; the random numbers come from a fixed seed so the run repeats).
| policy | wait after the n-th failure | on the page |
|---|---|---|
| immediate retry | none (1 tick) | 0 of 6 succeed, 24 calls, over at t = 4 |
| exponential backoff | min(cap, base × 2ⁿ) | 0 of 6 succeed, 24 calls, over at t = 15 |
| full jitter | random(0, min(cap, base × 2ⁿ)) | 6 of 6 succeed, 17 calls, over at t = 6 (the page draws 1 to the backoff) |
| equal jitter | half the backoff + random(0, half) | not shown: never retries very early |
| decorrelated jitter | min(cap, random(base, previous wait × 3)) | not shown: grows from the last wait |
Run Demo 4 to fill the results table with all three runs side by side.
Limits that go with retries
- Max attempts (or a total deadline): after it, give up and report the error instead of waiting forever.
- Retry only what can fail safely twice. A timed-out
POSTmay have worked; retrying it can charge a card twice unless the call is idempotent, for example with anIdempotency-Keyheader. - Retry only transient errors: timeouts,
503,429, connection resets. A400or404will fail the same way again. - Honour
Retry-Afterwhen the server sends it; it knows best when to come back. - Retry at one layer. If the app, the client library and a proxy each retry 3 times, one call can become 27.
- Retry budgets and circuit breakers cap retries as a share of all traffic, or stop calling a service that keeps failing.
See also Circuit Breaker and Bulkhead, which stops calls to a failing service altogether, Token Bucket vs Leaky Bucket for the server's side of 429 and Retry-After, and Backpressure for a consumer that cannot keep up. TCP Congestion Control uses the same idea: back off fast when the network is overloaded.
Retries are only safe when the server can tell a repeat from a new request: see Idempotency Keys.
A retry waits for a failure; a hedged request sends a second copy when a reply is merely slow and takes whichever answers first.
See also Redundancy and Availability: TMR, N-Version and the Nines for masking a fault with redundant modules and a voter instead of retrying.
What the page leaves out
Real time and timeouts (a call that hangs instead of failing fast); thousands of clients and retries at several layers; equal and decorrelated jitter (only in the table); Retry-After headers; retry budgets and hedged requests; a server whose recovery itself depends on the load (cold caches, connection pools filling up); and idempotency keys that make retried writes safe.