String matching
Given a text T of length n and a pattern P of length m, find every position where P occurs in T. This is what "Find" in an editor does, and what tools like grep and DNA-sequence searches are built on.
The naive method tries every shift s and compares P with T[s..s+m−1] character by character. On a mismatch it moves the pattern one place to the right and starts over from its first character. It forgets everything it just learned, so on inputs like T = AAAAAAAAAB, P = AAAB it makes about nm comparisons.
The KMP idea
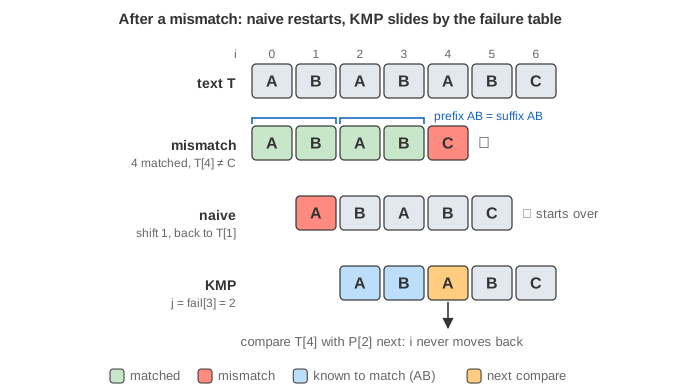
Suppose the first j pattern characters matched and then a mismatch happened. We already know the last j text characters: they are P[0..j−1]. The next shift that could possibly work lines up a prefix of the pattern with the end of those j characters. So the question "how far can we slide?" depends only on the pattern, and can be answered in advance.
The failure table (also called the prefix function) stores the answer: fail[j] is the length of the longest proper prefix of P[0..j] that is also a suffix of it. For P = ABABCABAB:
j        0  1  2  3  4  5  6  7  8
P[j]     A  B  A  B  C  A  B  A  B
fail[j]  0  0  1  2  0  1  2  3  4      (fail[3] = 2: "AB" is both a prefix and a suffix of "ABAB")
After a mismatch with j characters matched, KMP sets j = fail[j-1]: it slides the pattern so that the longest possible prefix is still matched, and compares the same text character again. The text position i never moves backwards.
kmpSearch(T, P):
    j = 0                                   // characters of P matched
    for i = 0 to n − 1:
        while j > 0 and T[i] ≠ P[j]:
            j = fail[j − 1]                 // slide the pattern
        if T[i] == P[j]:
            j = j + 1
        if j == m:
            report a match at i − m + 1
            j = fail[m − 1]                 // keep looking (matches may overlap)
Building the failure table
The table is built by running the same idea on the pattern itself. Keep len, the length of the prefix matched so far. When P[i] == P[len], the prefix grows by one: fail[i] = len + 1. When they differ, fall back to the next shorter candidate, len = fail[len-1], and try again. When len is already 0, fail[i] = 0. In the animation, P[i] is outlined and P[len] is blue.
Running time
Each comparison either moves i forward or slides the pattern forward, and neither can happen more than n times. So the search makes at most 2n comparisons, and building the table at most 2m: O(n + m) in total, compared with O(nm) for the naive method. At the end, the animation shows both comparison counts for your input. Try a repetitive text such as AAAAAAAAAAAAAAAAAAAAB with the pattern AAAAB to see the difference.
Worked example
Pattern P = ABABC. Its failure table: fail[2] = 1 because "A" is both a prefix and a suffix of "ABA", fail[3] = 2 because of "AB" in "ABAB", and fail[4] = 0 because nothing ending in C is a prefix.
j        0  1  2  3  4
P[j]     A  B  A  B  C
fail[j]  0  0  1  2  0
Now search the text T = ABABABC:
i=0..3   T[0..3] = ABAB matches P[0..3]            j = 4   (4 comparisons)
i=4      T[4] = A ≠ P[4] = C: mismatch with 4 matched
         slide: j = fail[3] = 2  ("AB" still matched), compare T[4] with P[2] = A: match, j = 3
i=5      T[5] = B = P[3]                           j = 4
i=6      T[6] = C = P[4]                           j = 5 = m: match at 6 − 5 + 1 = 2
KMP makes 8 comparisons and never looks at a text character before position 4 again. The naive method compares ABABC with ABABA (5 comparisons), then with BABAB (1), then with ABABC (5): 11 comparisons. On a long, repetitive text the difference grows to n + m against nm.
Common mistakes
- "Proper" prefix:
fail[j]is the longest prefix ofP[0..j]that is also a suffix but not the whole string. Otherwise every value would bej + 1and the pattern would never slide. - Do not advance i after a fallback. After
j = fail[j-1], the same text character is compared again with the newP[j]; only a match orj == 0moves on. - After a full match, continue with
j = fail[m-1], notj = 0, or overlapping matches are missed: inAAAAthe patternAAoccurs at 0, 1 and 2. - Some books store the table shifted by one (
π[0] = −1); the idea is the same, only the indices change.